
A perspective from Striped Donkey
Africa Has a Data Problem.
Synthetic City Twins Offer a Different Way Forward.
Africa does not need to wait for perfect data before it can build AI for African realities. But the answer is not synthetic data without evidence. It is synthetic data whose assumptions, relationships, history and limitations can be inspected.
In this article
Synthetic data is having a global moment.
Across artificial intelligence, machine learning, healthcare, financial services and software engineering, organizations are increasingly using artificially generated data to supplement real-world datasets, protect privacy, test systems and train models.
For Africa, however, the conversation is more complicated.
The continent does not simply face a shortage of AI-ready datasets. In many markets, important records remain fragmented across institutions, inconsistently digitized, difficult to access, expensive to obtain or legitimately restricted by privacy requirements.
That creates an uncomfortable paradox.
If a synthetic-data system depends heavily on abundant, representative real-world microdata, what happens when the very reason synthetic data is needed is that such data does not exist at sufficient scale?
And if poorly grounded synthetic data simply reproduces assumptions imported from somewhere else, have we solved Africa's data problem — or automated it?
These are valid concerns.
At STRIPED DONKEY, we believe they point toward a different architecture.
Not artificial survey respondents pretending to represent real Africans.
Not millions of plausible but disconnected rows.
And not synthetic data presented as a substitute for observed reality.
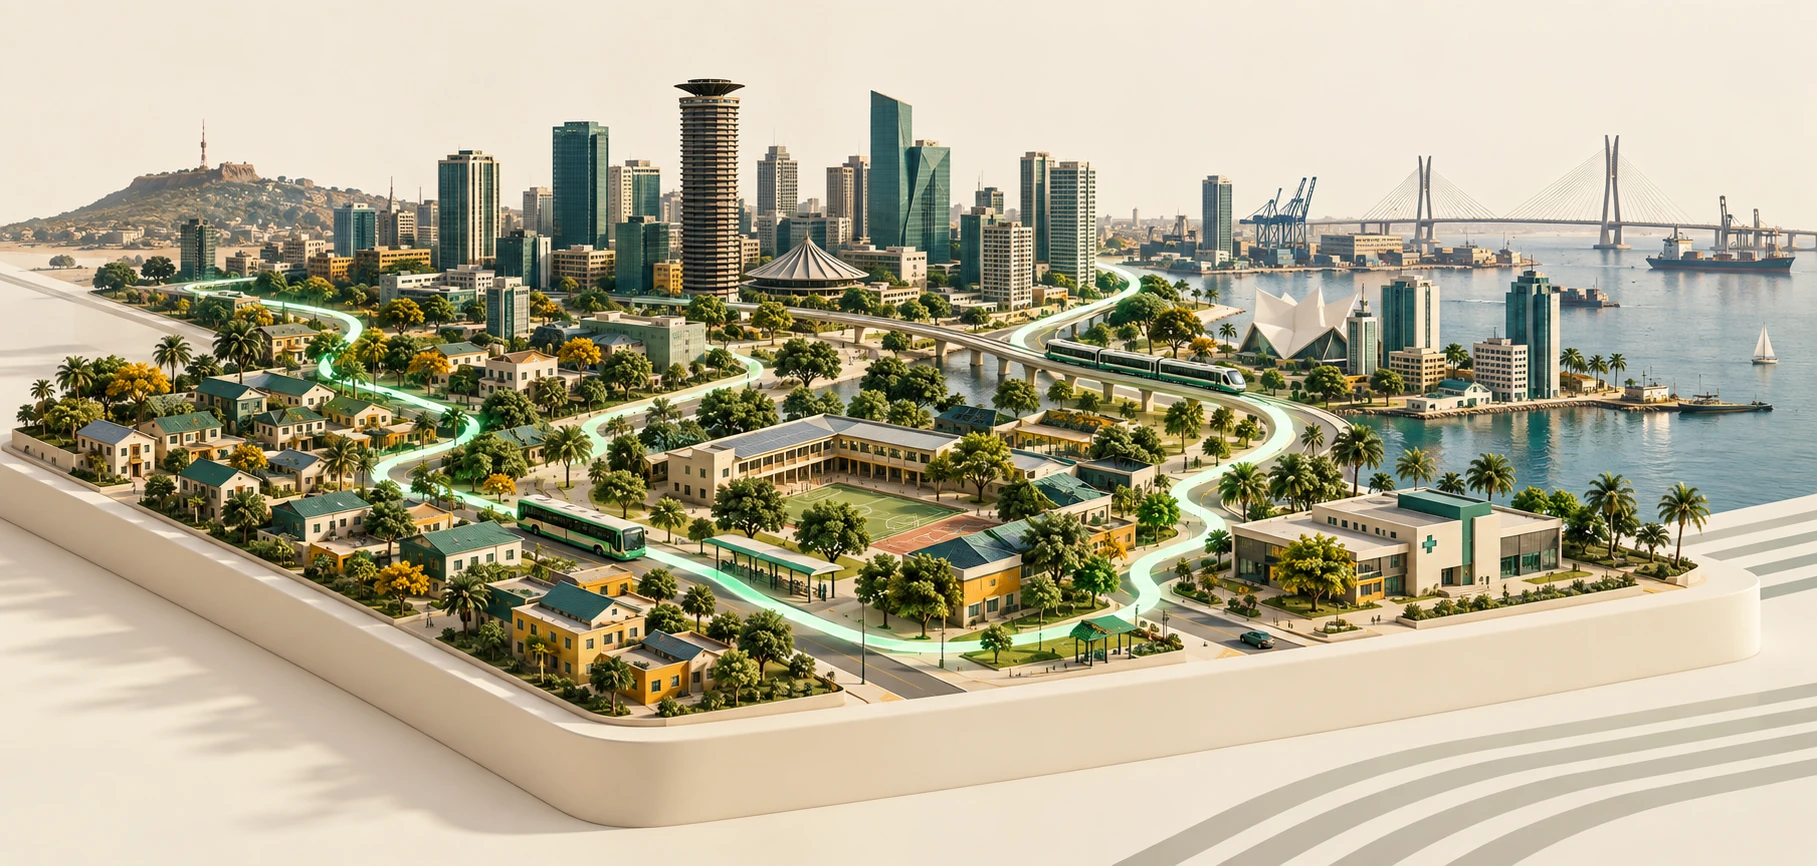
Instead, we are building Synthetic City Twins:
- persistent synthetic residents;
- households that exist through time;
- education histories that can precede employment;
- employment that can change;
- health events connected to broader life histories;
- and multiple domains linked to the same underlying synthetic population.
The technology behind this approach is the Fidelra City Twin Engine — FCTE.
Its central idea is simple:
One citizen. Many domains. Across time.
Africa's Data Problem Is Also a Connection Problem
Discussions about Africa's data gap usually focus on quantity.
Not enough health data.
Not enough employment data.
Not enough locally relevant training data.
Not enough longitudinal data.
But quantity is only part of the challenge.
The other problem is connection.
A health dataset may contain clinical encounters without employment history.
An employment dataset may contain occupations without educational pathways.
An education dataset may describe graduates without showing what happened to them afterward.
A transport dataset may record movement without household, economic or demographic context.
The datasets exist as islands.
Yet real cities do not work that way.
A person studies, enters the workforce, changes jobs, moves residence, joins a household, uses transport, becomes insured, visits a clinic, changes mobile providers, starts a business or experiences other life transitions.
Those events are connected because the person is connected.
For many AI, research and simulation problems, that continuity matters.
The question is therefore not simply:
How do we create more African data?
It is:
How do we create data in which relationships between people, households, institutions and events remain coherent through time?
That is the problem Synthetic City Twins are designed to explore.
One citizen. Many domains. Across time.
citizen
 Education
 Employment
 Health
 Insurance
 Household
 Transport
A Different Model of Synthetic Data
Synthetic data is not a single technology.
Some approaches learn the statistical distribution of an existing dataset and generate new records resembling it.
Others use simulation, probabilistic models, rules, generative AI or combinations of several techniques.
FCTE starts from a different premise.
The objective is not to reconstruct individual real people.
It is to create a fully synthetic population whose chronology, relationships and aggregate behaviour can be tested against explicit evidence, constraints and assumptions.
The architecture can be summarized as:
From evidence to connected data
- Published evidence and historical context
- Explicit assumptions, constraints and lifecycle rules
- Synthetic population and households
- Connected domain events through time
- Structural and temporal certification
- Empirical benchmarking
- Versioned research and machine-learning products
The distinction is important.
The claim is not:
“This synthetic resident represents a particular real resident.”
The relevant question is:
“Does this synthetic population behave coherently enough, and align closely enough with available evidence, for the intended analytical or engineering use?”
Those are fundamentally different standards.
From Rows to Lives
Consider employment.
A conventional employment dataset might contain:
- Age
- Education
- Occupation
- Income
- Employment Status
Such data can be useful.
But it says little about how someone arrived at that state.
A longitudinal city model can ask different questions:
- When did education end?
- When did employment begin?
- Was there a promotion?
- Was employment terminated?
- Did the resident later enter self-employment?
- Which qualifications existed at the time of an employment event?
- What happened next?
The same principle applies to healthcare.
Rather than generating an isolated diagnosis row, a connected model can retain the synthetic resident's earlier healthcare activity, household context, employment state, insurance position and later outcomes.
That changes the kinds of analytical questions the data can support.
Instead of asking only:
What percentage of this table has characteristic X?
we can begin asking:
What happened before X?
What happened afterward?
Which earlier conditions were associated with the transition?
Can a model trained on an earlier synthetic period predict a later synthetic outcome without leaking future information?
That is the difference between generating records and constructing a synthetic longitudinal environment.
Nairobi and Lagos: Building at City Scale
STRIPED DONKEY's first Synthetic City Twins are Nairobi, Kenya and Lagos, Nigeria.
The current city models contain approximately:
- 5.08 million synthetic Nairobi residents
- 26.39 million synthetic Lagos residents
Those numbers require an important qualification.
They are synthetic model population counts.
They are not official census estimates and should never be interpreted as direct measurements of the real cities.
That separation is deliberate.
The objective is not to blur simulation and observation.
It is to build sufficiently large synthetic populations for machine-learning development, longitudinal research, software engineering and controlled experimentation while maintaining a clear distinction between:
what was observed
and
what was simulated.
That boundary is essential to trust.
Time Changes Everything
A city is not a snapshot.
Neither should a city twin be.
The current FCTE architecture extends synthetic histories back to 1940, allowing later states to emerge within a historical sequence rather than appearing as isolated present-day records.
Why does this matter?
Because many outcomes are path-dependent.
Education systems change.
Industries change.
Households evolve.
Transport networks expand.
Technology adoption changes.
Healthcare systems develop.
Employment pathways shift.
A synthetic resident born decades ago should not simply inherit the same institutional environment as someone born recently.
Chronology therefore becomes a constraint.
A university completion must occur after enrollment.
Employment should not begin before the resident is eligible for it.
A promotion belongs inside a valid employment episode.
A person's age at an event must agree with their date of birth.
A historical machine-learning feature must not contain information that would only have become available later.
These rules sound obvious.
At millions of residents and potentially billions of connected records, maintaining them consistently becomes a serious engineering problem.
Generating Data Is Easy. Keeping It Coherent Is Hard.
This is why certification is part of FCTE's construction process, not simply a quality badge added at the end.
Checks can operate at several levels.
| Review area | Questions to ask |
|---|---|
| Structural integrity | Do required relationships exist? Are references valid? Are entities connected correctly? |
| Temporal integrity | Does cause precede effect? Do lifecycle events occur in possible sequences? Does historical data accidentally contain future information? |
| Domain consistency | Does a record obey the rules of the domain being modeled? |
| Cross-domain consistency | If education, employment, healthcare, insurance or other domains refer to the same synthetic resident, do those histories remain logically compatible? |
| Empirical grounding | Where credible external evidence exists, how do selected synthetic distributions compare against it? |
| Release integrity | Can a user verify exactly which files and artifacts belong to a particular release? |
The purpose is not to claim perfection.
It is to make the system inspectable.
A dataset should not become trustworthy simply because its creator describes it as realistic.
Users should have something concrete to examine.
Transparency Matters More Than Pretending to Be Perfect
The word realistic is often used too casually in synthetic data.
A dataset can be internally coherent but poorly calibrated against an important external statistic.
It can resemble one reference population while being inappropriate for another use.
It can be structurally correct while simplifying a real-world phenomenon.
It can be excellent for software testing and unsuitable for estimating an official population rate.
Those distinctions matter.
A certification PASS therefore does not mean:
This is reality.
It means:
A defined test was executed and its stated acceptance criteria were met.
Likewise, a disclosed limitation is not automatically a weakness.
It defines the boundary of the claim being made.
For synthetic data to earn serious adoption — particularly in healthcare, research, financial services and public-interest applications — that discipline will matter more than grand claims of perfect realism.
Privacy Without Pretending Risk Disappears
Privacy is another reason synthetic data matters.
A genuinely synthetic population can support many forms of experimentation without providing analysts with the personal records of actual residents.
Developers can test data pipelines.
Researchers can experiment with models.
Students can work with complex relational datasets.
Teams can prototype applications before accessing restricted production systems.
This can substantially reduce dependence on personally identifiable information.
But synthetic data does not magically eliminate every risk.
Poor assumptions remain possible.
Bias remains possible.
Misinterpretation remains possible.
Models can still be used outside their intended scope.
The stronger promise is therefore not:
Zero risk.
It is:
Useful data environments with greatly reduced dependence on identifiable personal records, combined with explicit governance, validation and limitations.
That is a more durable foundation.
What Synthetic City Twins Can Enable
Connected synthetic populations create useful possibilities across several fields.
Machine Learning
Teams can build and evaluate classification, regression, survival, forecasting and event-sequence models using datasets with explicit temporal structure.
AI Evaluation
Synthetic populations can provide controlled scenarios for evaluating agents, copilots, retrieval systems and automated decision-support workflows.
Software Engineering
Applications can be tested against large populations without filling development systems with copied production records.
Longitudinal Research
Researchers can explore transitions, sequences and outcomes rather than being restricted to isolated cross-sectional tables.
Education
Students can learn data science, statistics, database engineering and machine learning using complex datasets without needing access to sensitive citizen records.
Scenario Exploration
Synthetic environments can support what-if analysis, provided simulated results are clearly separated from forecasts of the real world.
Data-System Development
Governments, companies and nonprofits can prototype architectures, reporting systems and analytical pipelines before exposing them to sensitive operational information.
Synthetic data does not need to replace real-world data to be valuable.
In many cases, it simply needs to make experimentation possible where experimentation was previously difficult.
Synthetic Data Does Not Replace African Evidence
This may be the most important point.
Africa still needs better real-world data.
Better surveys.
Better administrative systems.
More digitization.
Stronger interoperability.
Improved statistical capacity.
More locally generated evidence.
Better privacy infrastructure.
Synthetic City Twins do not remove those needs.
A synthetic healthcare dataset should not replace epidemiological surveillance.
A synthetic employment model should not replace a labour-force survey.
A simulated population should never quietly become an official population statistic.
Real-world evidence remains essential because simulation needs something against which its assumptions and outcomes can be challenged.
The relationship should therefore be complementary:
Real-world evidence helps constrain simulation.
Simulation enables experimentation where real records are unavailable, restricted or unsuitable.
Differences between simulation and observation reveal where the model needs improvement.
That feedback loop is more valuable than pretending one can permanently substitute for the other.
Africa Does Not Need to Wait
The opposite extreme should also be challenged.
Africa should not be told that meaningful AI development must wait until every hospital, school, employer, transport system, government registry and household has produced decades of perfectly digitized microdata.
That could take generations.
Researchers need usable datasets now.
Universities need teaching data now.
African ML engineers need benchmark problems now.
Startups need development environments now.
Software teams need realistic test populations now.
The alternative to imperfect real-world data cannot be no experimentation at all.
This is where carefully governed synthetic systems can become infrastructure.
Not because they manufacture truth.
But because they create environments in which teams can ask questions, build systems, discover failure modes and identify what better real-world evidence is still required.
The Real Leapfrog Opportunity
Africa has leapfrogged infrastructure constraints before.
Mobile phones expanded without universal fixed-line networks.
Mobile money expanded financial access beyond traditional bank branches.
Cloud computing allowed organizations to build systems without owning data centres.
Synthetic City Twins offer another possibility.
But the leapfrog is not:
Skip reality and generate everything.
It is:
Move from data scarcity to governed experimentation while simultaneously improving the real evidence needed to validate those experiments.
That creates a cycle:
Evidence improves the next iteration
- Evidence
- Simulation
- Testing
- Measurement
- Better Evidence
- Better Simulation
Each iteration improves the next.
Each iteration improves the next.
And that may ultimately be why regions with significant data constraints become some of the most important places for synthetic-data innovation.
The problem is difficult.
That is exactly why it is worth solving.
The Standard We Want to Build Toward
The future of African synthetic data should not be judged by how many billions of rows can be generated.
The better questions are:
Can we explain what was simulated?
Can we explain which evidence informed it?
Can we distinguish evidence from assumption?
Can we trace events through time?
Can we test relationships across domains?
Can independent users inspect the release?
Can we disclose what the model does not know?
Can the same synthetic resident remain logically coherent across a lifetime?
If the answer increasingly becomes yes, synthetic data becomes more than generated information.
It becomes research and development infrastructure.
A Different Way Forward
Africa has a data problem.
Synthetic data alone will not solve it.
But data scarcity should not mean the continent must wait on the sidelines of the AI era.
There is another path.
Build synthetic environments.
Ground them in the best evidence available.
Preserve relationships.
Respect chronology.
Certify what can be tested.
Benchmark what can be measured.
Disclose what remains uncertain.
Maintain a clear boundary between simulation and observation.
And improve the model as better evidence becomes available.
That is the path STRIPED DONKEY is pursuing with FCTE.
Nairobi and Lagos are the beginning.
More cities are coming.
More domains will connect.
More assumptions will be tested.
More evidence will challenge the models.
And the models will continue to evolve.
Not synthetic data that pretends to know Africa.
Synthetic infrastructure built to help Africa ask better questions.
STRIPED DONKEY
Connected synthetic data for AI, machine learning and research.
Powered by FCTE — Fidelra City Twin Engine.
Nairobi. Lagos. More cities coming.